
MiniMax M3: Complete Guide to Variants, Pricing & FAQs
Comparison to similar models
Pricing insights
MiniMax M3.1 Flash
MiniMax M3 (Input)
MiniMax M3 (Output)
MiniMax M3 (Cached input tokens)
MiniMax Token Plan - Max
Pros & cons
Frequently Asked Questions
Is MiniMax M3 suitable for production?
How can I reduce MiniMax M3 costs?
Where can I find official pricing?
Conclusion
The MiniMax M3 series delivers high-performance large language model access optimized for production workloads. This guide covers variants, features, pricing, and practical tips to choose the right MiniMax M3 option for your use case.
Feature breakdown
MiniMax M3 models are designed for scalable inference with tiered options for input, output, and cached reads. Key technical and practical features include:
- High throughput for large token volumes.
- Separate pricing for input, output, and cached reads to optimize costs.
- Variants tuned for speed or cost efficiency such as the M3.1 Flash.
- Token plan bundles for heavy users offering predictable monthly usage.
Comparison to similar models
Compared with other LLM offerings, MiniMax M3 emphasizes competitive token pricing and multiple service integrations. In many deployments, its cached read option can dramatically reduce output costs for repeated queries compared to single-call models.
Pricing insights
Current public pricing examples gathered from official listings and providers:
| Item | Price / 1M tokens | Notes |
|---|---|---|
| MiniMax M3 (input) | $0.30 | Standard input token cost |
| MiniMax M3 (output) | $1.20 | Standard output token cost |
| MiniMax M3 (cached reads) | $0.06 | Cached input price to lower repeated-request costs |
| MiniMax M3.1 Flash (input/output/cache) | $0.15 / $0.60 / $0.015 | Listed as flash tier; examples show ~5% off in some marketplaces |
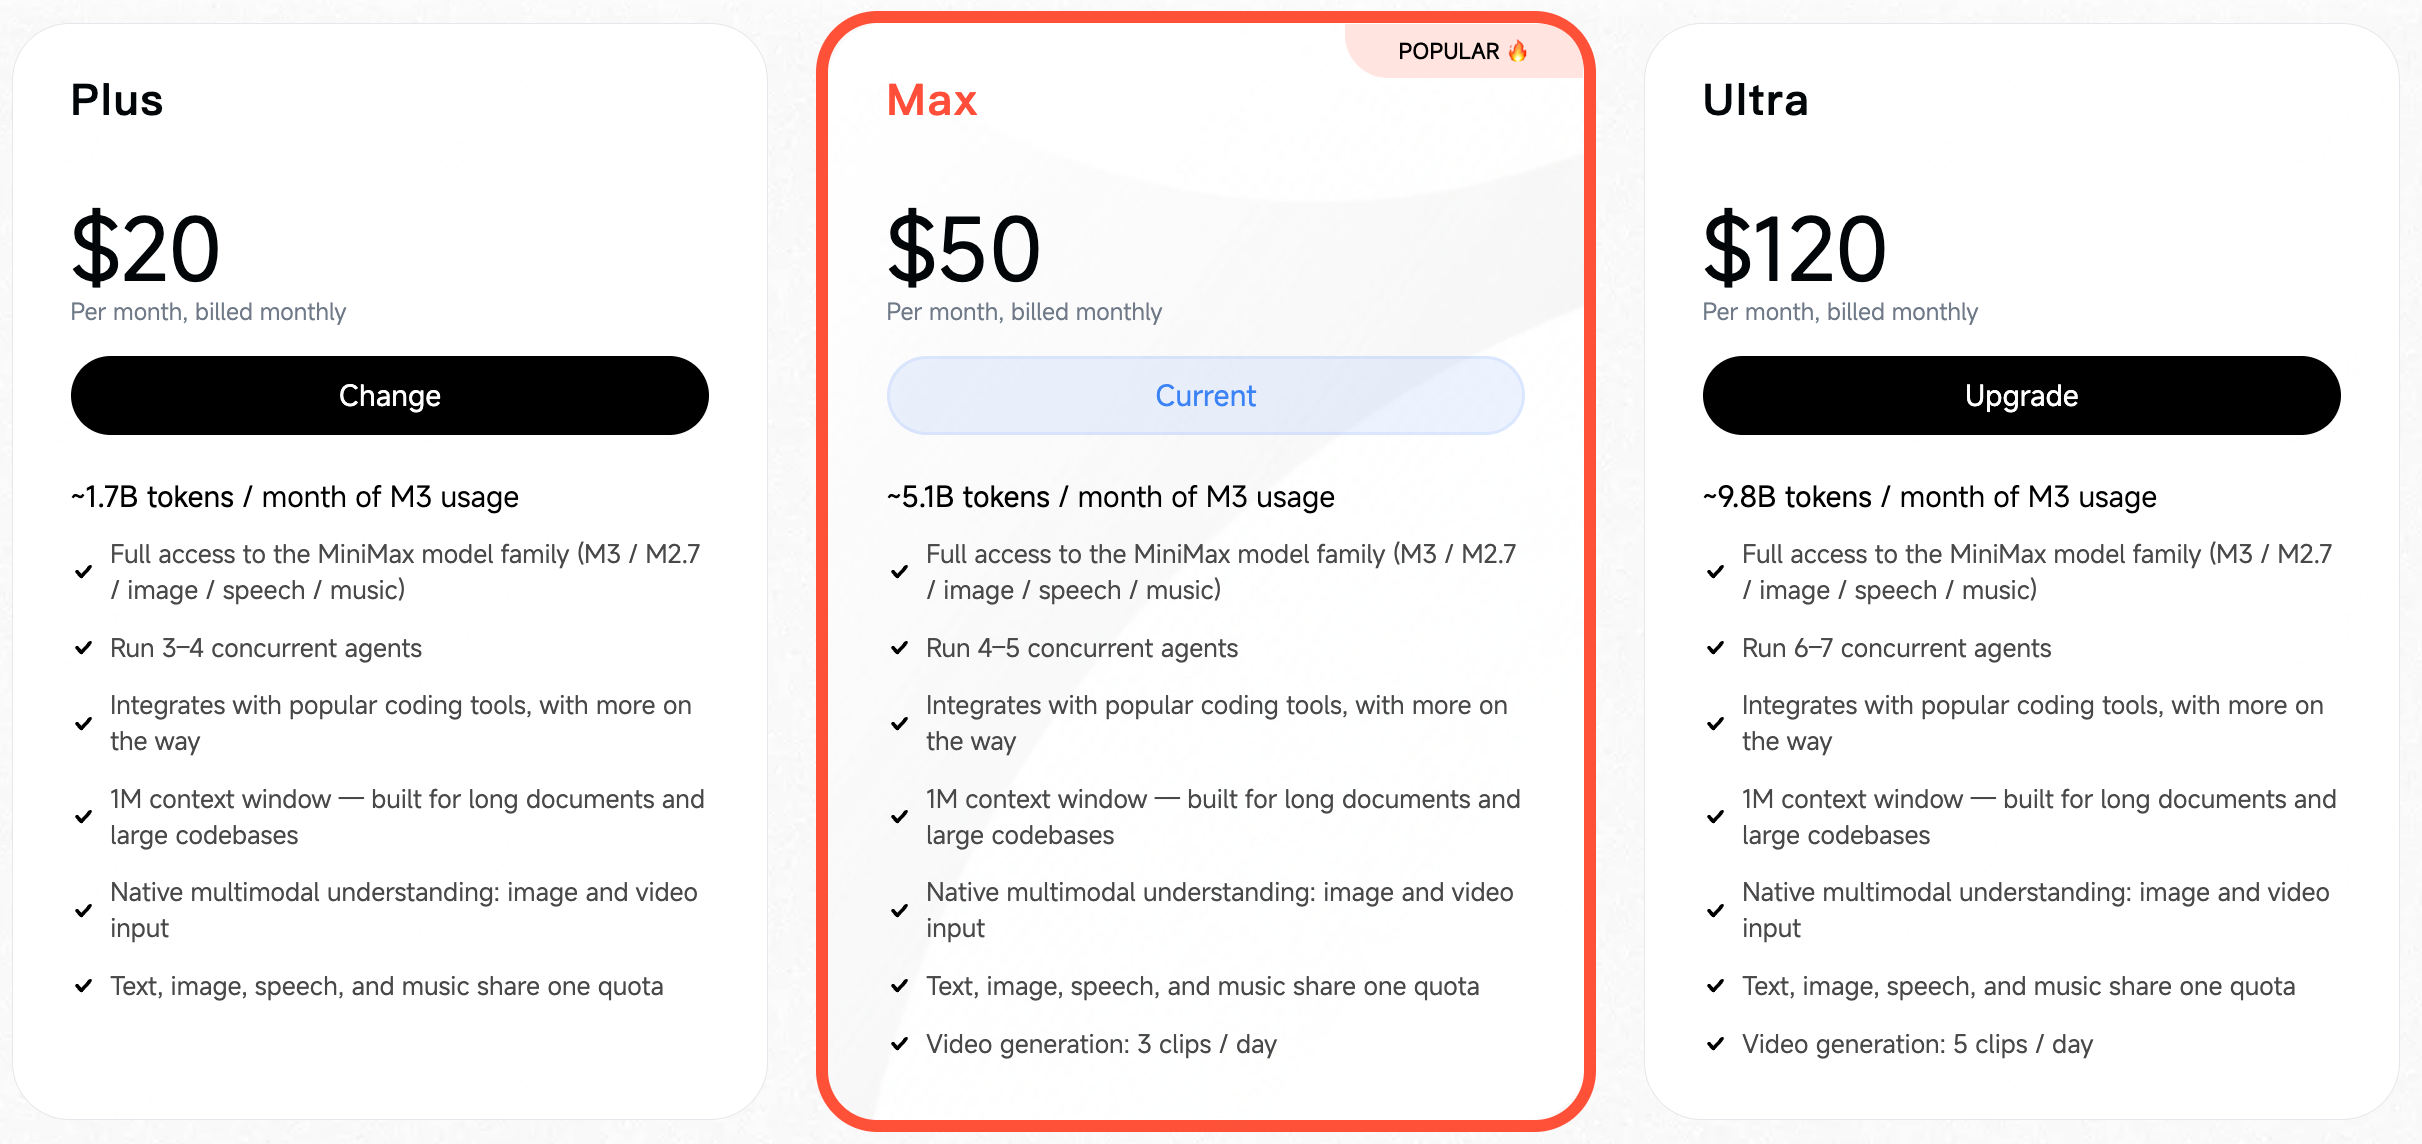
| MiniMax Token Plan - Max | ~$50 (plan) | Approximate bundle for high monthly token volumes (~5.1B) |
Promotions and marketplace discounts may apply; one listing advertises up to 75% off in limited promotions.
MiniMax M3.1 Flash
The M3.1 Flash tier is optimized for lower per‑token costs while preserving strong throughput, making it a good option for cost-sensitive production inference.
- Lower input/output/cache base prices compared with standard M3.
- Suited for high-volume, latency-tolerant workloads.
MiniMax M3 (Input)
The input-only listings reflect the cost to send tokens into the model. This is relevant for batch preprocessing and chaining multiple models.
- Typical input cost: $0.30 per 1M tokens.
MiniMax M3 (Output)
Output pricing governs the cost to generate responses. Output costs can dominate when responses are long or when streaming many tokens.
- Typical output cost: $1.20 per 1M tokens.
MiniMax M3 (Cached input tokens)
Cached reads provide an economical option for repeated identical queries by storing and reusing responses.
- Cached read example price: $0.06 per 1M tokens.
- Great for conversational agents with repeated prompts.
MiniMax Token Plan - Max
Token plans bundle large monthly quotas for sustained workloads and can reduce marginal costs for heavy usage.
- Example plan: ~5.1B tokens per month for approximately $50 in some listings.
Pros & cons
- Pros: Competitive tiered pricing; cached reads lower repeated costs; multiple provider integrations.
- Cons: Output tokens can be costly for long responses; pricing varies across marketplaces and requires careful monitoring.
Frequently Asked Questions
Is MiniMax M3 suitable for production?
Yes. Its tiered pricing and token plans make it adaptable for production workloads, especially when caching and batching are used.
How can I reduce MiniMax M3 costs?
Use cached reads for repeated queries, batch inputs, and choose flash tiers for cost-sensitive inference.
Where can I find official pricing?
Pricing is published on provider pages such as Together, GetMaxim, OpenRouter, and MiniMax official channels; marketplace discounts are occasionally available.
Conclusion
MiniMax M3 offers flexible options for teams needing scalable LLM inference. Evaluate flash tiers, caching, and token plans against your workload to optimize performance and cost. Explore provider listings and trials to test performance with your data.
Ready to try MiniMax M3? Check provider pages for up-to-date pricing and free trials to benchmark the model with your workloads.
Deals
Where to Buy:
openroutergetmaxim
together
minimax
Sale Price : $0.1425 / $0.57 / $0.01425 per 1M
Price Off : 5% off (per prices shown)
Percent Off : 5% off
In/Out/Cache read prices per 1M tokens. Listed list price was $0.15 (input) / $0.60 (output) / $0.015 (cache read); page shows 5% off pricing.
View : 0
Sale Price : $0.1425 / $0.57 / $0.01425 per 1M
Price Off : 5% off (per prices shown)
Percent Off : 5% off
In/Out/Cache read prices per 1M tokens. Listed list price was $0.15 (input) / $0.60 (output) / $0.015 (cache read); page shows 5% off pricing.
View : 0
Disclaimer: All product and company names and logos are trademarks™ or registered® trademarks of their respective holders. This content does not imply any affiliation with or endorsement by them. All information presented may not be accurate. Deals may have expired.
|
|
||||
|
|
||||
| Copyright © Echofavor 2026. All Rights Reserved. | Powered by Echofavor |
